The big idea: The fetch–decode–execute cycle has stages, and each uses different parts of the processor.
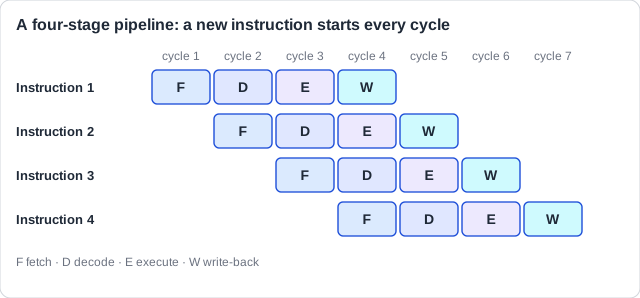
Pipelining overlaps them: while one instruction is executing, the next is being decoded and a third is being fetched. No stage sits idle waiting for the others.
The stages pipelining overlaps — fetch, decode, execute, each using different parts of the processor.
Interactive diagram
Explore the labelled diagram, charts and maps for this topic in full study mode.
The four stages of one instruction
Fetch
Copy the next instruction from memory into the CPU.
Decode
The control unit works out what the instruction means.
Execute
The ALU or other unit carries it out.
Write-back
The result is written to a register or to memory, ready for the next instruction.
Each stage uses different hardware, so all four can be busy at once.
Free preview
This is the free notes preview
You're reading the free notes. Aimnova Pro unlocks the full study experience — and you can try it with your first topic free to keep:
- FlashcardsLock in vocabulary and key terms with spaced repetition.
- Practice questionsAnswer exam-style questions and get instant AI marking.
- Mock exams & past-paper vaultSit full mocks and see exactly how examiners award marks.
- Personalised study planA daily plan built around your exam date and weak areas.
| Without pipelining | With a 3-stage pipeline | |
|---|---|---|
| Stages busy at once | One | Three |
| 3 instructions take | 9 stage-times | 5 stage-times |
| 100 instructions take | 300 | 102 |
| One instruction still takes | 3 stage-times | 3 — unchanged |
| What improves | Nothing | Throughput, not latency |
Throughput, not latency: Pipelining does not make any single instruction finish sooner — it still passes through every stage.
What improves is how many complete per second. This distinction is the most reliably examined point in the topic.
The laundry analogy, precisely: Washing, drying and folding one load takes the same time however you organise it. But you can dry load 1 while washing load 2.
The machines are the stages; one load is one instruction; four loads finish far sooner even though each still takes as long.
Memorize terms 3x faster
Smart flashcards show you cards right before you forget them. Perfect for definitions and key concepts.
Branches
- An if means the next instruction is not yet known
- The pipeline has already fetched the wrong ones
- They must be discarded and the pipeline refilled
- This is the expensive one
Data dependency
- An instruction needs the result of the one before it
- It must wait until that result exists
- The pipeline holds a bubble while it does
Resource conflict
- Two stages want the same hardware at once
- One waits — the other proceeds
- Eased by duplicating the contended unit
Branch prediction, and why it is a guess: Processors guess which way a branch will go and fetch accordingly. Guess right and nothing is lost; guess wrong and the pipeline must be flushed and refilled.
A deeper pipeline overlaps more — but a wrong guess then costs more, because there is more to throw away.
Pipelining: inside ONE core
- The stages of different instructions overlap
- More instructions finish per second (throughput)
Multi-core: MANY cores
- Each core has its own pipeline and runs its own thread
- The cores work independently and in parallel, e.g. four clips exported on four cores
- They only slow each other down when they share data or memory
How this is tested — you must compute the saving and be precise that throughput improves while latency does not. It comes up two ways:
Paper 1 Section A
- Describe the process of pipelining, 3-4 marks
- Calculate how long n instructions take
- State one cause of a stall
Paper 1 Section B — case study
- Explain why a branch is expensive
- Explain why one instruction is no faster
The classic trap: Saying pipelining "makes instructions faster". Each instruction takes exactly as long. More of them complete per second — that is throughput, not latency.
A processor has a 4-stage pipeline, each stage taking 1 ns. Determine how long 50 instructions take with and without pipelining, and explain why the saving is not 4×.
Model answer plan
See the answer broken into clear points, with guidance on how each point earns marks.